Large Language Models (LLMs) changed what Natural Language Processing can actually do. Applications that people once wrote off as too hard, or flat-out impossible with older methods, now ship. The reason is simple enough: these are deep learning models trained on huge piles of text, and they end up with a working grasp of how human language fits together. Feed one a prompt and it writes back something coherent, on-topic, and close to what a person would produce. Chat assistants, automated writing, sentiment analysis, translation. Behind most of the interesting NLP tools you have seen lately, an LLM is doing the heavy lifting.
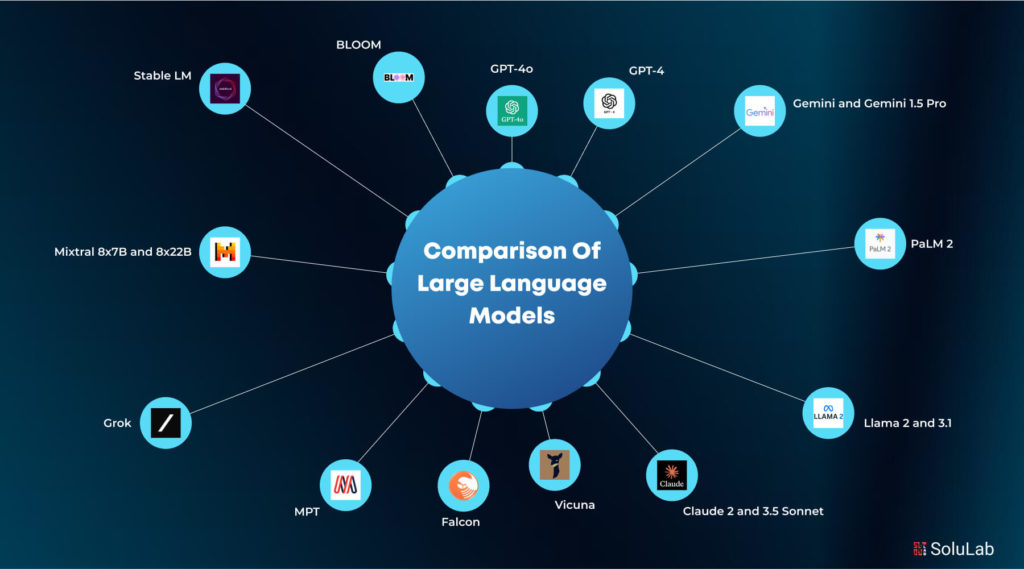
Picking the right one is the hard part. GPT, LLaMa, Flan-UL2, Bard, Bloom, and the list keeps growing.
All of them predict language well, which is why they are handy for writing and creative work. But the choice still trips people up. Should you reach for ChatGPT to polish an article, or lean on Notion AI to process notes? This blog tries to cut through that. We put a comparison of all LLMs side by side so you can pick the one that fits your work and your day. Writer, developer, marketer, or none of the above, if you want AI to actually help, treat this as your map through a field that will not sit still.
What are Large Language Models?
So what is an LLM, really? Strip away the hype and the LLM meaning is fairly plain: it is a foundational model trained on massive datasets. It reads and writes natural language, and that one ability lets it handle a surprising spread of tasks.
How does it get there? Through self-supervised and semi-supervised training, where the model absorbs statistical patterns from enormous text collections until those patterns become second nature. The headline use case is text generation, a kind of generative AI. The model looks at your input, then guesses the next token, then the next word, and keeps going.
Under the hood, LLMs behave a lot like neural networks. As of March 2024, the strongest models run a transformer design built only from decoders. A few newer ones borrow different architectures instead, recurrent neural networks, say, or Mamba, which is a state space model. Plenty of methods have been tried on NLP problems over the years. LLM AI learning, though, sticks to deep learning and nothing else. What these models do well is catch the tangled relationships between entities in a passage, then generate text that respects both the meaning and the grammar of language. And they can be pushed further with techniques like Retrieval Augmented Generation (RAG) to sharpen performance on a specific job.
Read Also: How to Create an Open-Source AI Model like Llama?
How Do LLMs Work?
At the core sits deep learning, and mostly transformer architectures like the Generative Pre-trained Transformer, or GPT. Transformers shine with sequential data such as text because they hold onto context across long stretches and track dependencies that sit far apart. Stack several layers of neural networks, each with tunable parameters, and you have the skeleton of an LLM. Training is what fills it in.
Here is the training loop, roughly. The model reads the words that came before and tries to predict the next one. To do that it hands out probability scores to tokenized words, which are just chunks of text sliced into shorter character sequences. Those tokens then become embeddings: numbers that carry the context of the text they came from.
Accuracy and robustness do not come cheap. LLMs get trained on text corpora so large they often run to billions of pages. That scale is the point. Grammar, meaning, the way concepts connect, all of it gets picked up through zero-shot and self-supervised learning. Read enough text and the patterns start to stick.
After training wraps, the model can write on its own. Give it an input and it predicts the next word, then the next sequence, drawing on everything it learned to keep the output coherent and on-context. That is what lets these models handle conversational AI and content generation without a human steering every sentence.
You can squeeze more out of a model, too. Prompt engineering, fine-tuning, and reinforcement learning with human feedback all help. They refine the outputs and chip away at problems like bias or plain inaccuracy, the kind of thing that creeps in when you train on messy, unstructured data at scale. Keep tuning the parameters and the training process, and the model gets more accurate and more dependable over time.
None of that matters for enterprise use without hard validation. Skip it and you invite liability, or a reputational mess. So the models go through thorough testing, checks against varied datasets, and a pass against ethical guidelines. Strip out the biases you can find, prove the thing holds up under pressure, and an LLM will run in the real world across all sorts of language work with real precision. In the comparison of Large Language Models, methods like LLMOPs are what make these models usable in practice, not just impressive on paper.
Key Technical Features of Large Language Models (LLMs)
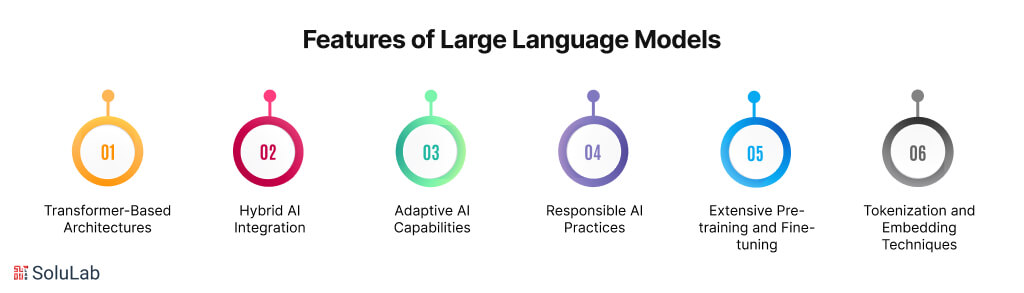
LLMs sit near the front of what AI can do right now, and a handful of technical traits explain why they are so good at natural language processing. Here are the ones that shape LLM development:
1. Transformer-Based Architectures
Transformers do most of the work. They handle sequential data with ease, and that is exactly what lets LLMs hold context and track long-range dependencies across a passage. The result is a model that reads and writes human language well.
2. Hybrid AI Integration
Many LLMs pull in hybrid AI approaches, mixing old-school rule-based systems with modern deep learning. That combination widens what a model can do and tightens its accuracy. It also lets the model borrow from both camps, the symbolic and the neural, which tends to produce something sturdier and easier to adapt.
3. Adaptive AI Capabilities
Then there is adaptability, one of the more striking traits of a modern LLM, and it hinges on adaptive AI capabilities. A model can shift its answers on the fly as new data and context arrive, so what comes back stays relevant and correct. That matters most when the environment or the user keeps changing, which, in practice, is where a static model starts to fail.
4. Responsible AI Practices
Teams building LLMs care more and more about responsible AI practices. In plain terms, that means baking in ways to cut bias, keep things fair, and stay transparent. It also means real ethical guidelines and validation steps, so the model does not spit out something harmful and stays roughly in line with what people expect.
5. Extensive Pre-training and Fine-tuning
The training happens in two phases. First, heavy pre-training on large-scale datasets. Then fine-tuning on the specific task at hand. That split is what lets an LLM stay general across domains while still getting sharp at one thing. Fine-tuning is the customization step, where you bend the model toward an industry’s quirks or a user’s actual needs.
6. Tokenization and Embedding Techniques
Before a model can read anything, it has to break the text apart. Tokenization does that, chopping text into smaller units, which then get turned into embeddings, numbers that carry semantic and contextual meaning. This is foundational. It is how an LLM ends up catching the nuance in the way people actually talk and write.
Put those traits together and you get a tool that is both powerful and flexible, one that can take on a broad set of natural language processing challenges. Hybrid AI, adaptive AI, responsible AI, whichever angle you take, LLM development keeps stretching what AI can do with human language.
Detailed Insights into Top LLMs
The field has moved fast, and it shows. There is now a wide spread of capable models, each with its own bent. Here is a closer look at the ones that come up most, with what they do and where they fit.
1. GPT-4o
Think of GPT-4o as GPT-4 on a diet. Same architecture, less compute. It was tuned for faster processing, which makes it the better pick when speed and efficiency actually matter for what you are building. In NLP vs. LLM debates, GPT-4o tends to come up as the efficient one: strong accuracy on NLP work without demanding a mountain of resources.
2. GPT-4
GPT-4 is one of the most capable LLMs OpenAI has put out, and it earned that reputation on language understanding and generation. It took what the earlier models did well and scaled it up, bigger datasets, smarter training. It writes text that reads like a person wrote it, answers questions, translates, and more. When people frame the LLM vs. generative AI question, GPT-4 is the easy example: coherent, on-context content across all sorts of domains, generative AI doing what it does best.
3. Gemini
Gemini was built to be a generalist, and it holds up across a range of NLP tasks. It pairs advanced transformer architectures with hybrid AI, so it can take on complicated language work and stay precise about it. Gemini LLM is known for how well it adapts, which is why you see it everywhere from conversational AI to niche industry cases. That hybrid streak, blending rule-based logic with deep learning, is a big part of why it performs.
4. Gemini 1.5 Pro
Gemini 1.5 Pro is the step up, tuned for enterprise work. More processing power, and features aimed at bigger jobs: better context awareness, real-time adaptability, multi-modal processing. If a business needs language processing that will not buckle under load, this is the one it reaches for. LLM vs. LAM comparisons keep pointing to its scale and its ability to juggle complexity, handling large, multi-domain tasks that leave older language models behind.
5. PaLM 2
PaLM 2, short for Pathways Language Model, comes from Google and was designed to work across formats. It takes in and puts out more than plain text. Images and even video are in play. It handles the tasks where you need to understand and generate language in several modes at once. That is the angle LLM vs. generative AI comparisons tend to seize on: PaLM 2 reaches past text-only generative AI, which makes it a flexible fit for a lot of jobs.
6. Llama 2
Llama 2 picks up where the first Llama left off, with better scalability and stronger performance. It was built to train and run efficiently, so it fits situations where resources are tight. In LLM vs. LAM talk, the point people keep raising is that Llama 2 chews through larger datasets and tougher tasks than the earlier, smaller language models.
7. Llama 3.1
Llama 3.1 pushes past Llama 2 on both scale and adaptability. It was built for high-performance NLP, and it earns its keep where accuracy and speed cannot slip. The architecture lets it work through massive datasets with barely any latency, which is why enterprise teams keep gravitating toward it.
8. Vicuna
Vicuna is the community favorite. Open-source, built out in the open, and unusually transparent about how it works. You give up a little polish and get a lot of access in return, since researchers and developers can crack it open and reshape the architecture for whatever they are building. LLM vs. generative AI comparisons often note how freely Vicuna generates language, a side effect of that open-source design, which keeps pulling in new ideas and tweaks.
9. Claude 2
Claude 2 comes from Anthropic, and safety was the design brief from the start. It leans hard on responsible AI techniques so its answers stay both accurate and ethical. Where it really shows up is conversational AI, giving back responses that hold context and read coherently. NLP vs. LLM comparisons keep circling back to its alignment work, which makes it the safer bet when the subject matter is sensitive or genuinely complicated.
10. Claude 3.5 Sonnet
Claude 3.5 Sonnet is the upgrade over Claude 2, with more processing power and sharper alignment. What sets it apart is memory across a conversation. It holds context over long exchanges, which makes it a natural fit for long-form dialogue and customer support. LLM vs. LAM discussions tend to single out how it manages tangled conversational flows, the kind that trip up older language models.
11. Falcon
Falcon is the speed model. It was built for real-time work where latency is the enemy, think voice assistants and interactive AI. In LLM vs. generative AI comparisons, the recurring note is that Falcon generates fast and still stays accurate, which makes it a go-to when you need quick, reliable answers and cannot afford to wait.
12. MPT (Multi-Path Transformer)
MPT runs on a multi-path transformer architecture, and that design is the whole story. It can handle several input paths at once, which helps it tackle complex tasks that call for parallel processing. In NLP vs. LLM comparisons, the focus lands on how well it juggles diverse data streams, making it a flexible option for messy language work.
13. Mixtral 8x7B
Mixtral 8x7B belongs to the Mixtral line, and it is the balanced one. At 7 billion parameters, it splits the difference between speed and accuracy, which suits mid-sized applications that need efficient language processing without a huge footprint. When people run LLM vs. LAM comparisons, they point out that it beats smaller language models while staying easy on resources.
14. Mixtral 8x22B
Mixtral 8x22B is the heavyweight of the series at 22 billion parameters. It was built for demanding work, the kind that involves large-scale data processing and leaves no room for accuracy to slip. LLM vs. generative AI discussions tend to stress how much more sophisticated and nuanced its language gets, which is what makes it a fit for advanced NLP tasks.
15. Grok
Grok is the one built for reasoning. It aims at tasks that need real comprehension of tricky ideas, then answers with something that actually adds up. LLM vs. generative AI comparisons usually cast Grok as a model that reaches past surface-level text, offering deeper analysis and content that reads the context. Building with Grok? You can get moving fast with a Grok API gateway that includes code examples for the common use cases.
16. StableLM
StableLM comes from Stability AI and is open-access, and the name is a promise: it stays steady across all kinds of applications. That reliability is why it fits research and development so well, giving you a stable base to experiment with what LLMs can do. NLP vs. LLM comparisons often flag how consistently it performs from one task to the next, which makes it a solid pick for researchers and developers alike.
17. BLOOM (BigScience Large Open-Science Open-access Multilingual Language Model)
BLOOM came out of the BigScience project as a multilingual model, built to cover a wide range of languages and cultural contexts. It is open-access, and inclusivity and global reach were baked into the goals from day one. LLM vs. generative AI comparisons tend to highlight how it generates text across many languages, which makes it a rare and genuinely useful resource in a global field.
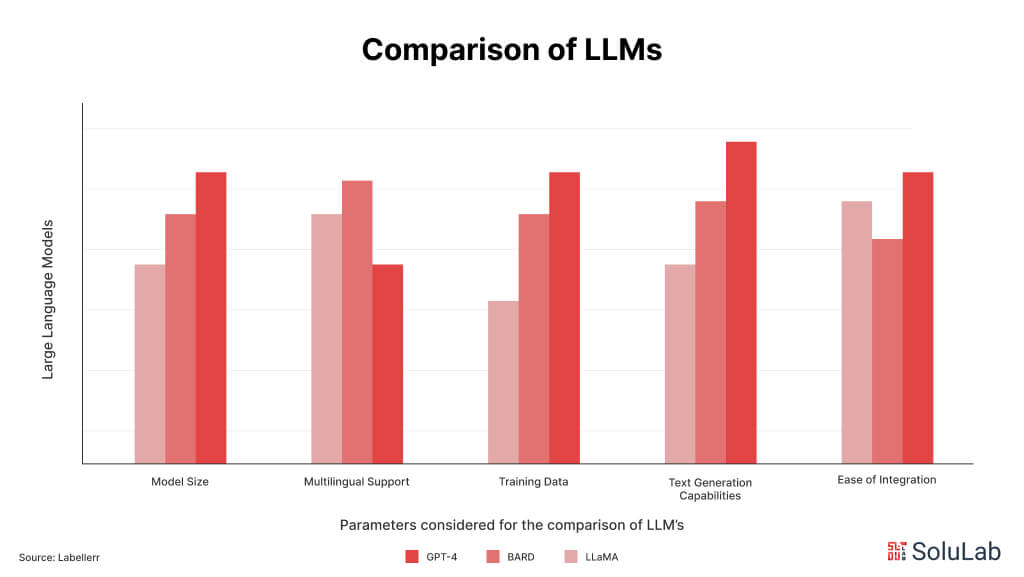
LLMs and Their Applications and Use Cases
LLMs have reshaped the AI industry, and the proof is in how many applications now run on them across sectors. With strong natural language processing under the hood, these models let businesses automate work, improve how customers are treated, and pull insight out of piles of data. Below, we walk through the leading LLM use cases and where they get used.
GPT-4 and GPT-4o
- Applications: GPT-4 and its leaner sibling, GPT-4o, lead the pack in AI-powered content creation, code generation, and conversational AI. Teams use them to build chatbots, virtual assistants, and AI agents that can take on real work: drafting documents, summarizing content, throwing out creative ideas.
- Use Cases: In legal work, GPT-4 can read a contract, summarize it, and flag where the risks hide. In healthcare, it backs up diagnostic work by explaining medical conditions in detail from patient records.
Gemini and Gemini 1.5 Pro
- Applications: The Gemini models are strong at multilingual translation, sentiment analysis, and personalized content. That makes them a fit for global marketing, where the translation has to be accurate and the content has to land in the local culture.
- Use Cases: E-commerce companies lean on Gemini for product recommendations tied to what a customer actually likes and does. On social media, the same models read user sentiment to tune content strategy.
PaLM 2
- Applications: PaLM 2 was built for the tasks that need high-level reasoning and real contextual grasp: hard question-answering, scientific research, technical documentation.
- Use Cases: In education, PaLM 2 powers intelligent tutoring systems that adapt to each learner. In finance, it reads market trends and helps shape investment strategies out of large datasets.
Llama 2 and Llama 3.1
- Applications: The Llama models are efficient at knowledge extraction, data synthesis, and domain-specific language modeling. Industries that have to process specialized information fast, legal, healthcare, academic research, put them to work.
- Use Cases: Law firms use Llama 2 for research, automating the hunt for relevant case law and statutes. Llama 3.1 shows up in scientific research, summarizing dense papers and helping generate hypotheses.
Vicuna
- Applications: Vicuna is at home in creative writing, storytelling, and dialogue for interactive apps like video games and virtual reality.
- Use Cases: Game developers use Vicuna to write dynamic, reactive dialogue for NPCs, the non-playable characters, in RPGs. In marketing, it turns out engaging copy for brand storytelling.
Claude 2 and Claude 3.5
- Applications: The Claude models were built for high-stakes decisions, ethical AI, and situations that call for deep context and a bit of empathy, mental health support, conflict resolution, that sort of thing.
- Use Cases: In customer service, Claude 2 helps AI agents handle knotty queries and resolve them with some warmth. Claude 3.5 turns up in teletherapy platforms, giving emotionally aware responses during counseling.
Falcon
- Applications: Falcon is tuned for high-speed processing and real-time decisions, which suits financial trading, supply chain optimization, and autonomous systems.
- Use Cases: In finance, Falcon drives high-frequency trading algorithms that decide in a split second off market data. In logistics, it reworks delivery routes in real time to cut costs and move faster.
MPT (Multi-Purpose Transformer)
- Applications: MPT is the utility player. It bends to a lot of tasks: natural language understanding, text classification, anomaly detection.
- Use Cases: In cybersecurity, MPT catches odd patterns in network traffic before they turn into a breach. In customer support, it sorts and ranks incoming queries so responses go out faster.
Mixtral 7×8 B and Mixtral 8X22B
- Applications: The Mixtral models are built for large-scale data analysis and model integration, feeding into AI-driven decisions, predictive analytics, and automated reporting.
- Use Cases: Manufacturers use Mixtral models to predict when equipment will fail and schedule maintenance before it does. In retail, the same models read consumer trends to forecast demand and keep inventory in check.
Grok
- Applications: Grok sharpens AI-powered insight in business intelligence, predictive analytics, and customer relationship management (CRM).
- Use Cases: In CRM, Grok helps a business see what a customer will want next and tailor the interaction, which lifts retention. It also does market research work, spotting new trends buried in unstructured data.
Stable LM
- Applications: Stable LM is tuned for the mission-critical stuff where consistency matters most: healthcare diagnostics, legal analysis, automated content moderation.
- Use Cases: In healthcare, Stable LM backs diagnostic tools that have to read medical data the same accurate way every time. In legal tech, it keeps document drafting and review consistent from one file to the next.
BLOOM
- Applications: BLOOM was aimed at biodiversity research, environmental monitoring, and sustainability, where its knack for chewing through scientific texts and large datasets pays off.
- Use Cases: Environmental agencies use BLOOM to track climate data and forecast ecological fallout. In agriculture, it helps fine-tune crop management by reading weather patterns and soil conditions.
Add all of this up and the LLM applications and use cases keep pushing both efficiency and fresh thinking across a lot of sectors. From sharpening AI agents to running heavy decision-making work, what these models can do keeps widening, and it opens the door to new AI use cases and the kind of applications that change how work gets done.
How SoluLab Can Help Transform Your Business Through LLMs?
At SoluLab, as an LLM development company, we put Large Language Models to work driving real innovation and efficiency across industries. We know LLM development and integration, and that lets businesses tap AI for a wide range of jobs, from taking routine tasks off people’s plates to deepening how they engage customers. Work with us and you can turn LLMs into a way to tighten operations, surface insight you can act on, and stand up intelligent systems built around what your business actually needs. Everything we ship is meant to be safe, to scale, and to fit where your company is trying to go.
We recently launched a project called InfuseNet that lets your team design intricate business logic without the usual headache. Its Flow interface is drag-and-drop, so you can wire multiple LLMs, templates, and media models to extraction tools and get a solid intelligent application out the other end. In minutes, not weeks, you can build a personalized ChatGPT-style app on your own data: register it, set up a knowledge base, drop it into workflows, and watch the operational load ease. InfuseNet pulls data in from databases, cloud storage, and APIs, gets it ready for fine-tuning with LLMs, and keeps it confidential in self-hosted deployments. Connect to MySQL, Google Cloud, and your CRMs, and you get secure, high-performance AI solutions that actually move the business forward. Ready to build with advanced LLMs? Reach out and we will get you started.
FAQs
Shipra Garg is a tech-focused content strategist and copywriter specializing in Web3, blockchain, and artificial intelligence. She has worked with startups and enterprise teams to craft high-conversion content that bridges deep tech with business impact. Her work translates complex innovations into clear, credible, and engaging narratives that drive growth and build trust in emerging tech markets.